Dremio is now part of SAP

Alex Merced

Head of DevRel, Dremio

Alex Merced is Head of DevRel for Dremio, a developer, and a seasoned instructor with a rich professional background. Having worked with companies like GenEd Systems, Crossfield Digital, CampusGuard, and General Assembly.

Alex is a co-author of the O’Reilly Book “Apache Iceberg: The Definitive Guide.”  With a deep understanding of the subject matter, Alex has shared his insights as a speaker at events including Data Day Texas, OSA Con, P99Conf and Data Council.

Driven by a profound passion for technology, Alex has been instrumental in disseminating his knowledge through various platforms. His tech content can be found in blogs, videos, and his podcasts, Datanation and Web Dev 101.

Moreover, Alex Merced has made contributions to the JavaScript and Python communities by developing a range of libraries. Notable examples include SencilloDB, CoquitoJS, and dremio-simple-query, among others.
Alex Merced's Articles and Resources

Apache Iceberg 1.12 and Iceberg Rust 0.11 preview shown as two icebergsApache Iceberg 1.12 and Iceberg Rust 0.11 preview shown as two icebergs

Blog Post

Preview of Upcoming Apache Iceberg 1.12 and Iceberg Rust 0.11: New Features and Breaking Changes

Apache Iceberg 1.12 and Iceberg Rust 0.11 bring geospatial types, Variant improvements, encryption, V4 groundwork, and breaking changes teams should test now.

Read more ->

Blog Post

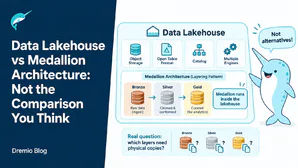
Data Lakehouse vs Medallion Architecture: Not the Comparison You Think

These are not competing choices. One describes what your platform is made of, the other describes how you organise tables inside it. The costly decision is the copy count.

Read more ->

Blog Post

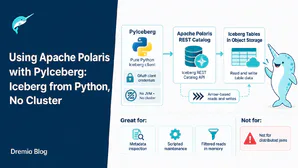
Using Apache Polaris with PyIceberg: Iceberg from Python, No Cluster

PyIceberg reads and writes Iceberg from Python with no JVM. Here is how to point it at Apache Polaris, and the metadata work that makes it worth keeping installed.

Read more ->

Blog Post

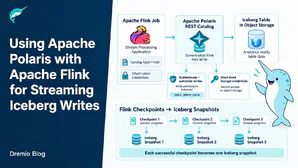
Using Apache Polaris with Apache Flink for Streaming Iceberg Writes

Flink writes Iceberg tables through a catalog. Here is how to wire it to Apache Polaris, and why the checkpoint interval is the most consequential setting in the whole pipeline.

Read more ->

Blog Post

Apache Iceberg Orphan File Cleanup: Finding Files Your Table Forgot

Orphan files are invisible to snapshot expiration and can quietly quadruple your storage. Here is how cleanup finds them, and how to run it without deleting a live table.

Read more ->

Blog Post

Apache Iceberg Snapshot Expiration: What It Deletes and When to Run It

Snapshot expiration is what makes a delete in Apache Iceberg reduce your storage bill. Here is what it removes, what it refuses to remove, and how to run it without losing rollback.

Read more ->

Blog Post

Apache Iceberg Manifest Files Explained

A manifest file is an Avro file listing data files that belong to an Apache Iceberg table, along with per-column statistics for each one. Manifests are why Iceberg can plan a query without listing directories: the engine reads partition summaries in the manifest list to skip whole manifests, then reads column bounds inside the survivors […]

Read more ->

Blog Post

The Apache Polaris REST API: How Engines Talk to the Catalog

Apache Polaris implements the Iceberg REST Catalog specification, a set of HTTP endpoints that any Iceberg client can speak. The specification covers namespace and table management, an atomic commit protocol built on assertions rather than locks, server-side scan planning, and three different ways for a client to obtain storage access. Because the contract is the […]

Read more ->

Blog Post

Choosing an Apache Iceberg Catalog: Polaris, Gravitino, Unity, Lakekeeper and More

Choosing an Apache Iceberg catalog comes down to three questions, and the feature matrices most vendors publish do not help with any of them. Do you need more than one engine to write to the same tables? Do you need governance you do not control to be predictable? And do you need to keep the […]

Read more ->

Blog Post

Access Control in Apache Polaris: RBAC and Credential Vending

Apache Polaris controls access through role-based access control with four levels: a privilege is granted to a catalog role, the catalog role is granted to a principal role, and the principal role is assigned to a principal. Privileges never attach to a person directly. The two privileges that matter most, TABLE_READ_DATA and TABLE_WRITE_DATA, are the […]

Read more ->

Blog Post

Apache Polaris Architecture Explained

Apache Polaris is a catalog service for Apache Iceberg. It answers the question “which files make up this table right now, and are you allowed to touch them?” Its architecture has four moving parts: an entity model that nests catalogs, namespaces and tables inside a realm, a persistence layer that stores those entities and their […]

Read more ->

Blog Post

State of the Open Lakehouse, September 2026

Five Apache projects sit underneath most open lakehouses running in production today. Four of them were there a year ago. The fifth, Apache Ossie, entered the Apache Incubator in June 2026 and has not cut its first release yet. That is the fastest way to describe what changed this year. The stack did not get […]

Read more ->

Blog Post

Migrating to Apache Iceberg: Strategies for Every Source System

This is Part 15, the final article of a 15-part Apache Iceberg Masterclass. Part 14 covered hands-on Dremio Cloud. This article covers the three migration strategies and how to execute a zero-downtime migration using the view swap pattern. Most organizations do not start with Iceberg. They have years of data in Hive tables, data warehouses, CSV files, databases, […]

Read more ->

Blog Post

Hands-On with Apache Iceberg Using Dremio Cloud

This is Part 14 of a 15-part Apache Iceberg Masterclass. Part 13 covered streaming approaches. This article is a practical walkthrough of working with Iceberg on Dremio Cloud, covering table creation, data ingestion, optimization, semantic layer construction, and AI-powered analytics. Table of Contents Getting Started Running this walkthrough: Dremio Cloud is no longer self-serve. To use it, contact the […]

Read more ->

Blog Post

Approaches to Streaming Data into Apache Iceberg Tables

This is Part 13 of a 15-part Apache Iceberg Masterclass. Part 12 covered Python and MPP engines. This article covers the three primary approaches to streaming data into Iceberg tables and the operational trade-offs each creates. Iceberg was designed for batch analytics, but most production data arrives continuously. Streaming ingestion bridges this gap by committing data to Iceberg […]

Read more ->

Blog Post

Using Apache Iceberg with Python and MPP Query Engines

This is Part 12 of a 15-part Apache Iceberg Masterclass. Part 11 covered metadata tables. This article covers the two main ways to access Iceberg data: directly from Python libraries and through MPP (massively parallel processing) query engines. Table of Contents The Python Ecosystem for Iceberg PyIceberg: Native Python Access PyIceberg is the official Python library for Apache […]

Read more ->

Blog Post

Apache Iceberg Metadata Tables: Querying the Internals

This is Part 11 of a 15-part Apache Iceberg Masterclass. Part 10 covered maintenance operations. This article covers the metadata tables that let you inspect Iceberg table internals using standard SQL. Iceberg exposes its internal metadata as queryable virtual tables. You can use them to check table health, debug performance issues, audit changes, and build monitoring dashboards. No […]

Read more ->

Blog Post

Maintaining Apache Iceberg Tables: Compaction, Expiry, and Cleanup

This is Part 10 of a 15-part Apache Iceberg Masterclass. Part 9 covered how tables degrade. This article covers the four maintenance operations that keep Iceberg tables healthy and the three approaches to running them. Table of Contents The Four Maintenance Operations 1. Compaction (File Rewriting) Compaction reads small files, merges them into optimally-sized files (128-512 MB), and […]

Read more ->

Blog Post

How Data Lake Table Storage Degrades Over Time

This is Part 9 of a 15-part Apache Iceberg Masterclass. Part 8 covered embedded catalogs. This article explains the five ways Iceberg table storage degrades and how to detect each problem before it impacts query performance. An Iceberg table that works well on day one will not work well on day 365 without maintenance. Every append, update, and […]

Read more ->

Blog Post

When Catalogs Are Embedded in Storage

This is Part 8 of a 15-part Apache Iceberg Masterclass. Part 7 covered the traditional catalog landscape. This article examines a newer approach: embedding the catalog directly inside the storage layer. Traditional Iceberg architectures have three components: the query engine, a standalone catalog, and object storage. Embedded catalogs collapse the catalog into the storage layer itself, reducing the […]

Read more ->

Blog Post

What Are Lakehouse Catalogs? The Role of Catalogs in Apache Iceberg

This is Part 7 of a 15-part Apache Iceberg Masterclass. Part 6 covered the write process and explained how the catalog enables atomic commits. This article covers what catalogs are, why they matter, and how to choose between the many options available in 2026. A lakehouse catalog is the component that answers one question: “Where is the current […]

Read more ->

Blog Post

Enterprise Agentic Analytics Explained

Enterprise data rarely sits in one place. It spreads across a warehouse, a few databases, an object store, and a handful of SaaS tools, each with its own access rules. Enterprise agentic analytics is the practice of letting AI agents work across all of that, running the multi-step analysis a human analyst used to do […]

Read more ->

Blog Post

Agentic Analytics Benefits and Key Features

Most enterprise data teams are buried. A business user files a ticket for a number, waits three days, gets a dashboard that almost answers the question, then files another ticket to adjust it. Enterprise agentic analytics breaks that loop by putting AI agents to work directly on governed data, so the person who has the […]

Read more ->

Blog Post

Writing to an Apache Iceberg Table: How Commits and ACID Actually Work

This is Part 6 of a 15-part Apache Iceberg Masterclass. Part 5 covered hidden partitioning. This article walks through the exact steps an engine takes when writing data to an Iceberg table, when the write becomes visible, and how concurrent writers are handled. Understanding the write process is critical because it explains why Iceberg can provide ACID guarantees […]

Read more ->

Blog Post

Agentic Lakehouse: The Architecture Built for AI-Native Analytics

The Agentic Lakehouse solves a problem that most data teams haven’t fully articulated yet: the architecture you built for human analysts is the wrong architecture for AI agents. A traditional lakehouse is optimized for predictable SQL from BI tools, tuned by DBAs who know the query patterns, and governed through access controls that assume a human is […]

Read more ->

Blog Post

Text-to-SQL vs Agentic Analytics: What the Upgrade Requires

The BIRD benchmark, the leading academic evaluation for text-to-SQL systems, shows that even the best large language models achieve only 60-70% accuracy on complex SQL queries against realistic database schemas. On simple, single-table lookups, accuracy approaches 90%. On multi-join, multi-condition queries that require real business context, it falls off a cliff. That gap is the starting […]

Read more ->

Blog Post

Semantic Layer vs Data Catalog: What’s the Difference?

These two terms show up in almost every data platform conversation, and they are often used interchangeably. Both deal with metadata. Both aim to make data more understandable to humans and machines. But they serve fundamentally different purposes, sit in completely different places in your architecture, and solving one problem does not solve the other. […]

Read more ->
Hidden Partitioning: How Iceberg Eliminates Accidental Full Table ScansHidden Partitioning: How Iceberg Eliminates Accidental Full Table Scans

Blog Post

Hidden Partitioning: How Iceberg Eliminates Accidental Full Table Scans

This is Part 5 of a 15-part Apache Iceberg Masterclass. Part 4 covered partition evolution. This article covers hidden partitioning, the feature that ensures users never need to know how their data is physically organized. The most expensive mistake in data lake querying is the accidental full table scan: a query that reads every file because the user […]

Read more ->

Blog Post

Semantic Layer Governance: Control What AI Agents Access

AI agents can execute hundreds of queries per minute, with no human reviewing each result before the agent acts on it. That is the governance gap that most data architecture teams have not yet closed. Traditional access controls were designed for a world where a person ran a report, read the output, and made a […]

Read more ->

Blog Post

Semantic Layer for AI Agents: Stop Getting the Numbers Wrong

An AI agent that confidently returns the wrong revenue number is more dangerous than one that returns no number at all. Wrong answers that look plausible get acted on. They end up in board decks, budget decisions, and quarterly reports before anyone notices the refunds were never excluded. This is the real problem with AI […]

Read more ->
get started

Get Started Free

No time limit - totally free - just the way you like it.

Sign Up Now
demo on demand

See Dremio in Action

Not ready to get started today? See the platform in action.

Watch Demo
talk expert

Talk to an Expert

Not sure where to start? Get your questions answered fast.

Contact Us

Make data engineers and analysts 10x more productive

Boost efficiency with AI-powered agents, faster coding for engineers, instant insights for analysts.