Featured Articles
Popular Articles
-
 Dremio Blog: Open Data Insights
Governing Apache Ossie Semantic Models in Apache Polaris: APIs, Privileges, and Scope
-
 Dremio Blog: Open Data Insights
Operating Apache Polaris with the Admin Tool: Bootstrap, Purge, and Metastore Maintenance
-
 Dremio Blog: Open Data Insights
Running Apache Polaris with MongoDB: NoSQL Persistence, Bootstrap, and Maintenance
-
 Dremio Blog: Open Data Insights
Atomic CTAS and RTAS with Apache Iceberg: Catalog Choice, Staging, and Rollback
Browse All Blog Articles
-
 Dremio Blog: Open Data Insights
Governing Apache Ossie Semantic Models in Apache Polaris: APIs, Privileges, and Scope
Enable and govern Apache Ossie semantic models in Apache Polaris, understand beta APIs and privilege scopes, and design a controlled publication workflow. -
 Dremio Blog: Open Data Insights
Operating Apache Polaris with the Admin Tool: Bootstrap, Purge, and Metastore Maintenance
Use the Apache Polaris Admin Tool for bootstrap, purge, and NoSQL metastore maintenance with version matching, protected credentials, and verified runbooks. -
 Dremio Blog: Open Data Insights
Running Apache Polaris with MongoDB: NoSQL Persistence, Bootstrap, and Maintenance
Configure Apache Polaris with MongoDB persistence, bootstrap the metastore, run required NoSQL maintenance, and evaluate the current production tradeoffs. -
 Dremio Blog: Open Data Insights
Atomic CTAS and RTAS with Apache Iceberg: Catalog Choice, Staging, and Rollback
Understand when Iceberg CTAS and RTAS are atomic, how SparkCatalog differs from SparkSessionCatalog, what RTAS preserves, and how to test rollback. -
 Dremio Blog: Open Data Insights
Parquet Bloom Filters in Apache Iceberg: Configuration, Selectivity, and Row-Group Skipping
Configure Parquet Bloom filters for Iceberg columns, choose selective predicates, measure row-group skipping, and avoid memory and file-size waste. -
 Dremio Blog: Open Data Insights
Apache Iceberg Partition Statistics: compute_partition_stats, Pruning, and Query Planning
Compute Iceberg partition statistics incrementally, understand their metadata model, validate pruning, and separate them from column NDV statistics. -
 Dremio Blog: Open Data Insights
PostgreSQL CDC into Apache Iceberg with OLake Go and Apache Polaris
Stream PostgreSQL CDC into Apache Iceberg with OLake Go and Apache Polaris, including REST catalog OAuth, vended credentials, resumable state, and validation. -
 Dremio Blog: Open Data Insights
Relocating Apache Iceberg Tables with rewrite_table_path: Buckets, Regions, and Recovery
Use Iceberg rewrite_table_path to stage relocation across buckets or regions, copy files safely, validate metadata, and preserve a recovery path. -
 Dremio Blog: Open Data Insights
Rate-Limiting Iceberg Structured Streaming: Micro-Batches, Async Planning, and Snapshot Safety
Control Iceberg Spark Structured Streaming with micro-batch file and row limits, async planning, checkpoint safety, and overwrite handling. -
 Dremio Blog: Open Data Insights
Continuous Apache Iceberg Table Maintenance with Flink: Compaction, Expiration, and Locks
Run continuous Apache Iceberg maintenance with Flink using post-commit compaction, snapshot expiration, orphan cleanup, scheduling controls, and locks. -
 Dremio Blog: Open Data Insights
Apache Polaris with Open Policy Agent: External Authorization, Rego, and Safe Rollout
Connect Apache Polaris to Open Policy Agent, model authorization in Rego, configure secure calls, test every operation, and roll out external policy safely. -
 Dremio Blog: Open Data Insights
Apache Polaris Setup as Code: Export, Dry-Run, and Apply with YAML
Manage Apache Polaris setup as code with YAML export, dry-run validation, repeatable apply workflows, review gates, and clear limits on reconciliation. -
 Dremio Blog: Open Data Insights
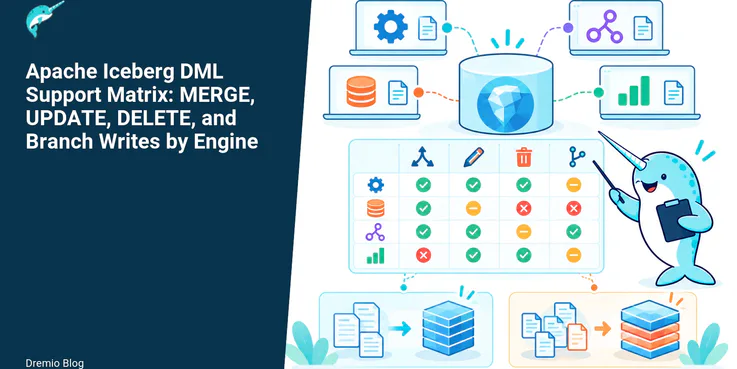
Apache Iceberg DML Support Matrix: MERGE, UPDATE, DELETE, and Branch Writes by Engine
Iceberg DML support is an engine capability, not a table-format checkbox. Spark documents MERGE, UPDATE, DELETE, overwrite, and branch writes. Trino documents write operations and MERGE through its Iceberg connector. Dremio documents MERGE, UPDATE, and DELETE for Iceberg tables, with source-specific branch limits. Flink's Iceberg integration emphasizes INSERT, overwrite, upsert sinks, and branch-targeted writes rather than a universal SQL MERGE surface.
-
 Dremio Blog: Open Data Insights
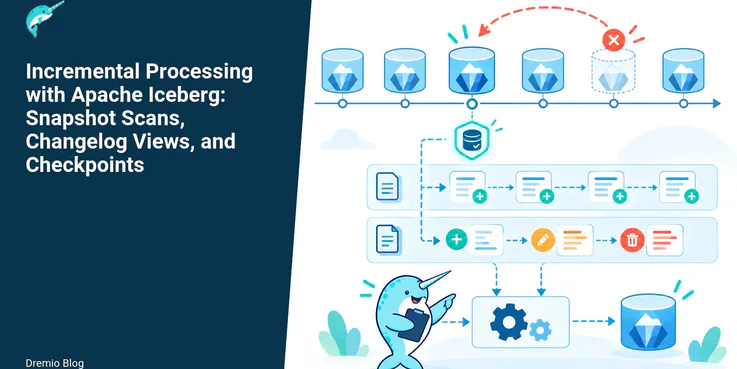
Incremental Processing with Apache Iceberg: Snapshot Scans, Changelog Views, and Checkpoints
Iceberg incremental processing reads a bounded snapshot range and stores the last successfully applied snapshot as a checkpoint. Append scans work for append-only changes. Changelog scans or engine-specific change views are needed when updates and deletes matter. A reliable pipeline treats snapshot expiration, branch ancestry, checkpoint writes, and replay idempotency as part of the design.
-
 Dremio Blog: Open Data Insights
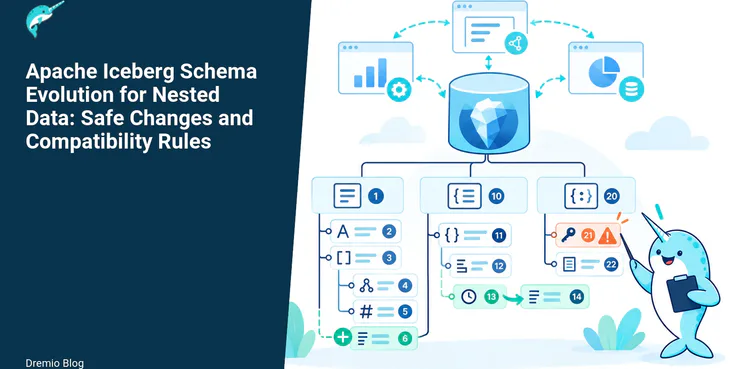
Apache Iceberg Schema Evolution for Nested Data: Safe Changes and Compatibility Rules
Iceberg evolves nested schemas by stable field ID rather than by column position. You can add, drop, rename, reorder, and promote supported field types without rewriting data, including fields inside structs. The unsafe edges are map-key changes, incompatible type conversions, required-field changes without valid defaults, and clients that do not honor Iceberg field IDs correctly.
- 1
- 2
- 3
- …
- 50
- Next Page »