The Dremio Blog
Dremio Blog: Open Data Insights
-

 Dremio Blog: Open Data Insights
Apache Iceberg DML Support Matrix: MERGE, UPDATE, DELETE, and Branch Writes by Engine
Iceberg DML support is an engine capability, not a table-format checkbox. Spark documents MERGE, UPDATE, DELETE, overwrite, and branch writes. Trino documents write operations and MERGE through its Iceberg connector. Dremio documents MERGE, UPDATE, and DELETE for Iceberg tables, with source-specific branch limits. Flink's Iceberg integration emphasizes INSERT, overwrite, upsert sinks, and branch-targeted writes rather than a universal SQL MERGE surface.
-
 Dremio Blog: Open Data Insights
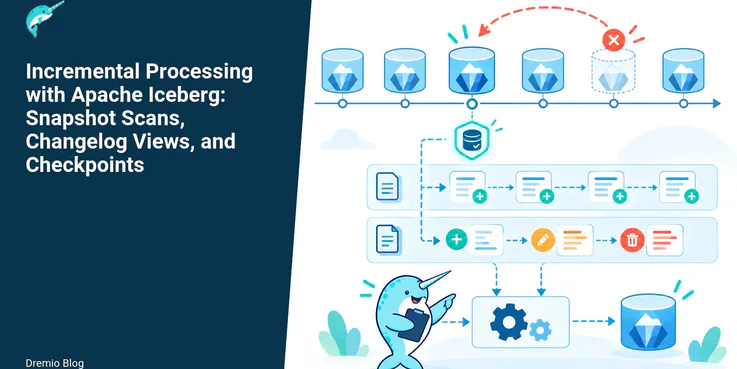
Incremental Processing with Apache Iceberg: Snapshot Scans, Changelog Views, and Checkpoints
Iceberg incremental processing reads a bounded snapshot range and stores the last successfully applied snapshot as a checkpoint. Append scans work for append-only changes. Changelog scans or engine-specific change views are needed when updates and deletes matter. A reliable pipeline treats snapshot expiration, branch ancestry, checkpoint writes, and replay idempotency as part of the design.
-
 Dremio Blog: Open Data Insights
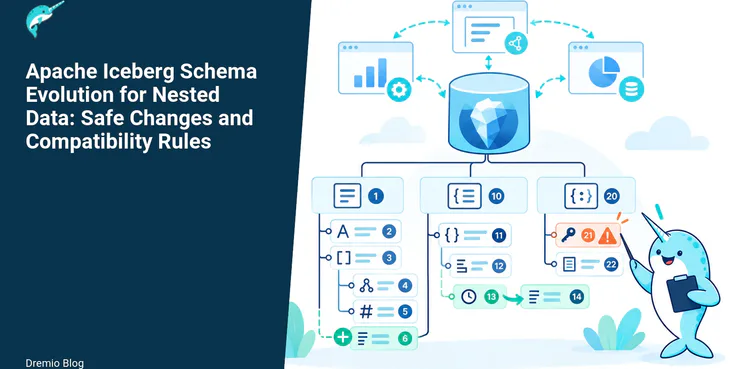
Apache Iceberg Schema Evolution for Nested Data: Safe Changes and Compatibility Rules
Iceberg evolves nested schemas by stable field ID rather than by column position. You can add, drop, rename, reorder, and promote supported field types without rewriting data, including fields inside structs. The unsafe edges are map-key changes, incompatible type conversions, required-field changes without valid defaults, and clients that do not honor Iceberg field IDs correctly.
-
 Dremio Blog: Open Data Insights
Apache Iceberg Clustering and Sort Order Evolution: When to Rewrite Data
Changing an Iceberg sort order is a metadata operation that affects new writes. It does not rearrange existing files. Rewrite old data only when query evidence shows that poor clustering creates enough scan cost to repay the rewrite. Start with high-value predicates, compare file pruning before and after a bounded rewrite, then expand only if the measured gain survives realistic workloads.
-
Dremio Blog: Open Data Insights
Apache Iceberg Write Distribution Modes: None, Hash, Range, and File Sizing
Iceberg write distribution controls how records reach writer tasks. None leaves distribution to the incoming plan, hash groups rows by partition values, and range globally orders rows by partition and sort keys. Hash is the normal starting point for partitioned tables. Range costs more but can improve clustering and pruning. File size still depends on task sizing because in-memory rows do not map directly to compressed file bytes.
-
Dremio Blog: Open Data Insights
Upgrading Apache Polaris in Production: Schema Migrations, Rolling Changes, and Rollback
A safe Polaris upgrade treats the application, persistence schema, authentication behavior, and client compatibility as separate gates. Read every intermediate release note, back up the persistence layer, test the exact upgrade path, apply required schema or index changes, canary the new version, and prove that rollback remains possible before expanding the deployment.
-
Dremio Blog: Open Data Insights
Migrating from Nessie to Apache Polaris Without Rewriting Iceberg Data
An Iceberg catalog migration can often reuse existing data and metadata files because the catalog stores table pointers rather than row data. The hard work is preserving namespaces, properties, current metadata locations, access controls, branches or tags that lack a direct equivalent, and a rollback path. Freeze writes, inventory references, migrate registrations, validate reads and writes, then move clients in controlled waves.
-
Dremio Blog: Open Data Insights
Sizing Apache Polaris for Production: Load Testing, PostgreSQL Pools, and Helm Resources
There is no universal Polaris replica count. Size the service from a representative mix of authentication, catalog lookup, commit, scan-planning, and policy operations. Increase concurrency until latency or error budgets fail, then tune application replicas, CPU and memory requests, PostgreSQL connection pools, and database capacity as one system rather than as independent knobs.
-
Dremio Blog: Open Data Insights
Apache Polaris Service Principals: Machine Identity, Secret Rotation, and Least Privilege
A Polaris service principal gives an application its own identity instead of borrowing a person's credentials. Give each workload a separate principal, map it to narrowly scoped principal roles, grant only the catalog roles it needs, store secrets in a managed secret system, and rotate credentials with an overlap window that proves both old and new clients behave as expected.
-
Dremio Blog: Open Data Insights
Apache Polaris with Spark 4: REST Catalog, OAuth, and Credential Vending
Spark 4 connects to Apache Polaris through Iceberg's RESTCatalog. The working configuration aligns the Polaris catalog URI, OAuth token endpoint, client credentials, scope, warehouse, and the vended-credentials header. Verify the connection with a namespace, table write, read-back, and a check that temporary storage credentials are not exposed in logs.
-
Dremio Blog: Open Data Insights
Troubleshooting Apache Polaris REST API Authentication: 401, 403, Token, and Role Errors
A Polaris 401 usually means the request did not present a token the service could validate. A 403 usually means authentication succeeded but the mapped principal lacks the required privilege. Debug the path in order: token issuance, issuer and audience validation, principal mapping, principal-role grants, catalog-role grants, and the requested operation.
-
Dremio Blog: Open Data Insights
Observing Apache Polaris with Prometheus, OpenTelemetry, and Jaeger
Apache Polaris exposes Micrometer metrics on its management interface and can emit OpenTelemetry traces when operators enable the relevant Quarkus settings. A useful deployment scrapes metrics, preserves X-Request-ID across gateways, samples traces deliberately, and alerts on user-visible symptoms instead of raw infrastructure noise.
-
Dremio Blog: Open Data Insights
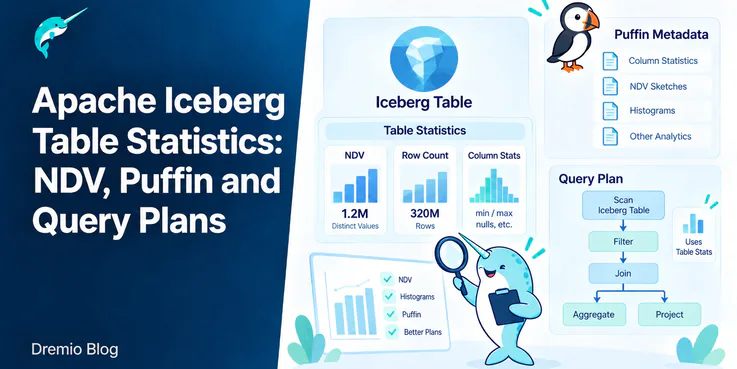
Apache Iceberg Table Statistics: NDV, Puffin and Query Plans
Iceberg keeps per-file bounds automatically but table-level NDV statistics only when you compute them. Why that decides join order, and how to keep them fresh.
-
Dremio Blog: Open Data Insights
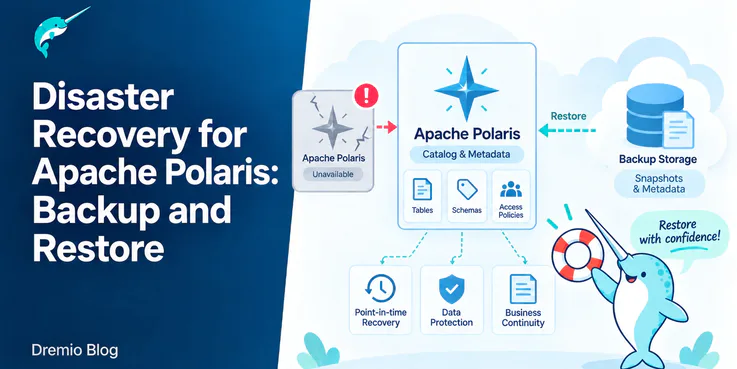
Disaster Recovery for Apache Polaris: Backup and Restore
Recovering Polaris means recovering a metastore and object storage separately. What to back up, the order to restore in, and the failure mode nobody plans for.
-
Dremio Blog: Open Data Insights
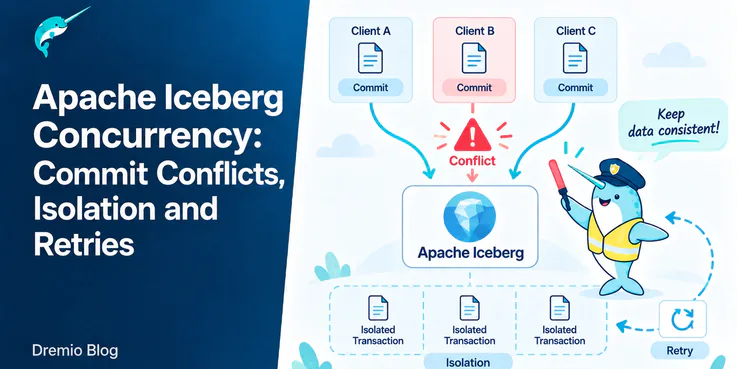
Apache Iceberg Concurrency: Commit Conflicts, Isolation and Retries
What causes an Iceberg commit conflict, the retry properties that govern it, the two isolation levels, and how to design conflicts out of a busy table.



- 1
- 2
- 3
- …
- 18
- Next Page »