The Dremio Blog
Dremio Blog: Open Data Insights
-

 Dremio Blog: Open Data Insights
Apache Polaris Generic Tables for Delta Lake and Non-Iceberg Assets
Polaris generic tables register non-Iceberg assets with a name, location, format, and properties so they can participate in catalog discovery and access workflows. They do not turn Delta Lake or another format into Iceberg, coordinate that format's commits, update its transaction log, or automatically vend credentials. The current feature is beta and should be framed as catalog registration, not full table-format governance.
-
 Dremio Blog: Open Data Insights
Apache Polaris Policies for Compaction, Retention, and Table Maintenance
Apache Polaris policies attach maintenance intent to catalog resources. Built-in policy types cover data compaction, metadata compaction, orphan-file removal, and snapshot expiry. A policy records configuration and inheritance, while a separate execution service must discover, schedule, run, and report the maintenance work. Treat policy storage and task execution as two distinct production components.
-
 Dremio Blog: Open Data Insights
Apache Polaris with Trino: Configuration, Security, and Operations
Trino connects to Polaris through its Iceberg connector with the REST catalog type. The core settings are the Polaris catalog URI, warehouse name, OAuth credential, token scope, and vended-credential support. Once Polaris grants and storage permissions align, Trino can discover, read, and write the same Iceberg tables used by other REST-compatible engines.
-
 Dremio Blog: Open Data Insights
Apache Polaris with DuckDB and iceberg-rust: Native Iceberg Clients
DuckDB and iceberg-rust can both use an Iceberg REST catalog such as Polaris without a JVM. DuckDB offers SQL-first local analytics through its Iceberg extension. iceberg-rust provides native Rust APIs for applications and services. They share the REST contract and object storage, but their feature coverage and operational roles differ enough that compatibility must be tested separately.
-
Dremio Blog: Open Data Insights
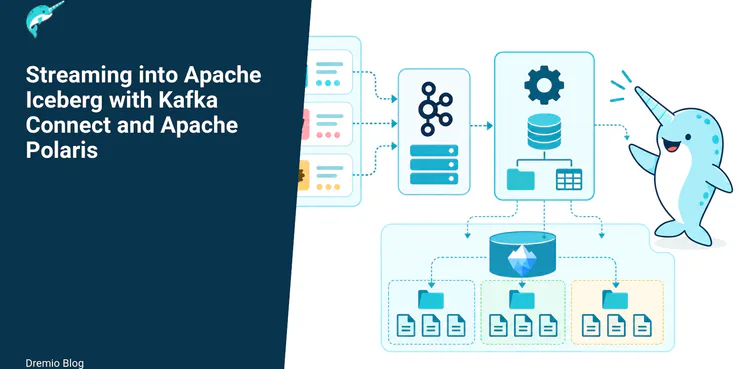
Streaming into Apache Iceberg with Kafka Connect and Apache Polaris
An Iceberg Kafka Connect sink writes Kafka records into Iceberg data files and commits them through a catalog. With Polaris, the connector uses the Iceberg REST interface for table metadata and OAuth-based authorization. A production setup must align topic routing, schema evolution, commit intervals, dead-letter handling, storage credentials, and maintenance because connector health alone does not prove that table snapshots are advancing.
-
Dremio Blog: Open Data Insights
Migrating AWS Glue and S3 Tables Catalogs to Apache Polaris
Moving from AWS Glue or Amazon S3 Tables to Polaris is a catalog migration, a permissions migration, and sometimes a storage migration. Existing Iceberg data can often remain in place when Polaris can register the table metadata and access its location. S3 Tables require a separate decision because table buckets are managed resources with their own endpoints, permissions, and service behavior. Do not treat the two source systems as one cutover path.
-
Dremio Blog: Open Data Insights
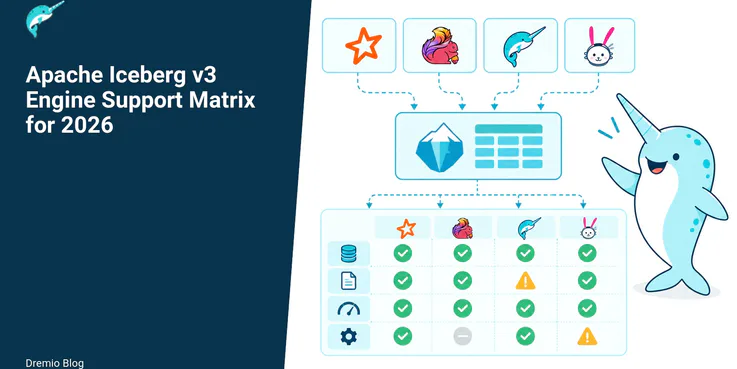
Apache Iceberg v3 Engine Support Matrix for 2026
Iceberg v3 support must be evaluated by feature, operation, and engine version. A product may open a v3 table yet reject deletion vectors, geometry, variant values, encryption, or writes. This matrix records documented support as of September 22, 2026 and separates table-level read, table-level write, and individual v3 capabilities so teams can choose the lowest common denominator deliberately.
-
Dremio Blog: Open Data Insights
How to Measure Data Lakehouse Vendor Lock-In with the Exit Cost Test
Vendor lock-in is the cost and risk of changing a provider, not the presence of a contract or a proprietary feature. The Exit Cost Test measures that cost across data format, catalog metadata, identity and policy, SQL and APIs, operations, egress, and organizational retraining. A platform is easier to exit when another engine can read the same bytes, discover the same tables, reproduce controls, and take over writes in a tested amount of time.
-
Dremio Blog: Open Data Insights
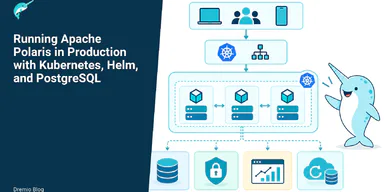
Running Apache Polaris in Production with Kubernetes, Helm, and PostgreSQL
A production Polaris deployment needs a durable relational persistence layer, repeatable schema initialization and migration, externalized secrets, TLS, health probes, metrics, backups, and a tested upgrade path. The official Helm chart supplies Kubernetes resources, but production readiness comes from the values, database operations, identity configuration, and failure testing around the chart.
-
Dremio Blog: Open Data Insights
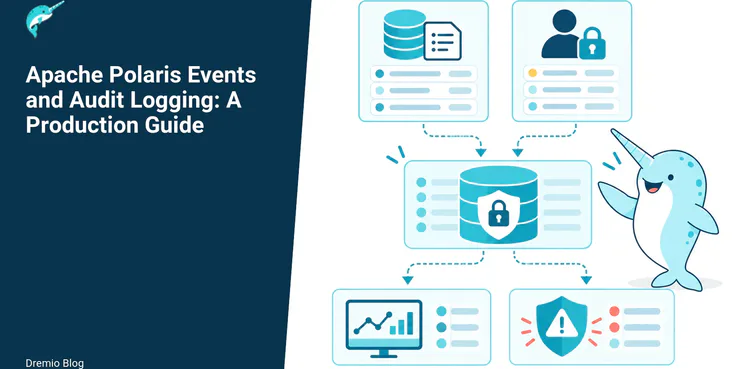
Apache Polaris Events and Audit Logging: A Production Guide
Polaris event listeners turn catalog and security activity into records that an external logging system can retain and analyze. A production design captures who acted, what resource changed, the result, request identifiers, and timing, while excluding credentials and limiting sensitive metadata. Audit value comes from durable export, normalized identity, retention, and tested alerts, not from enabling a listener alone.
-
Dremio Blog: Open Data Insights
Preview of Upcoming Apache Iceberg 1.12 and Iceberg Rust 0.11: New Features and Breaking Changes
Apache Iceberg 1.12 and Iceberg Rust 0.11 are close to the finish line, and neither one is a routine patch. Apache Iceberg 1.12.0 for Java carries 210 merged pull requests on its milestone. Iceberg Rust 0.11.0 packs roughly two months of work, including end-to-end table encryption and Variant support. Both went through release candidate trouble in mid-September 2026, which tells you something about how much changed.
-
Dremio Blog: Open Data Insights
Apache Iceberg Manifest Files Explained
A manifest file is an Avro file listing data files that belong to an Apache Iceberg table, along with per-column statistics for each one. Manifests are why Iceberg can plan a query without listing directories: the engine reads partition summaries in the manifest list to skip whole manifests, then reads column bounds inside the survivors to skip individual files. Neither stage touches your data.
-
Dremio Blog: Open Data Insights
The Apache Polaris REST API: How Engines Talk to the Catalog
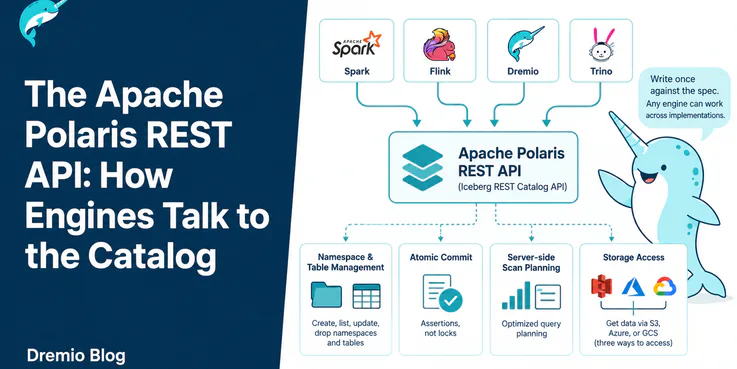
Apache Polaris implements the Iceberg REST Catalog specification, a set of HTTP endpoints that any Iceberg client can speak. The specification covers namespace and table management, an atomic commit protocol built on assertions rather than locks, server-side scan planning, and three different ways for a client to obtain storage access. Because the contract is the specification rather than a vendor SDK, an engine written against one implementation works against all of them.
-
Dremio Blog: Open Data Insights
Choosing an Apache Iceberg Catalog: Polaris, Gravitino, Unity, Lakekeeper and More
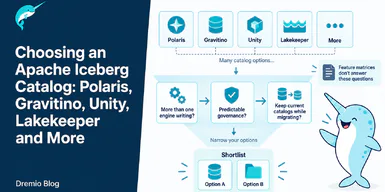
Choosing an Apache Iceberg catalog comes down to three questions, and the feature matrices most vendors publish do not help with any of them. Do you need more than one engine to write to the same tables? Do you need governance you do not control to be predictable? And do you need to keep the catalogs you already run while you migrate? Answer those and the field narrows from seven options to about two.
-
Dremio Blog: Open Data Insights
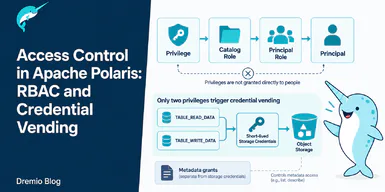
Access Control in Apache Polaris: RBAC and Credential Vending
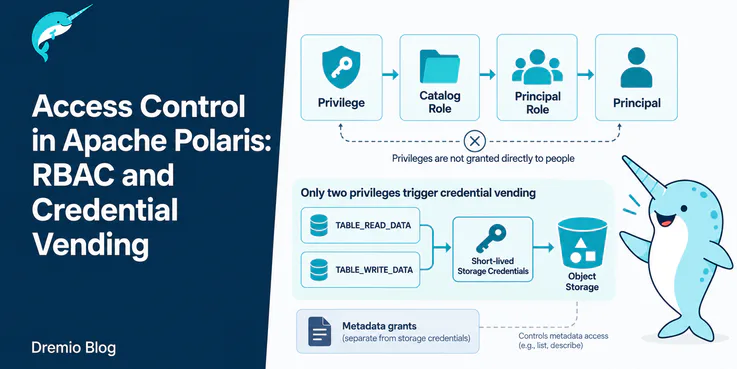
Apache Polaris controls access through role-based access control with four levels: a privilege is granted to a catalog role, the catalog role is granted to a principal role, and the principal role is assigned to a principal. Privileges never attach to a person directly. The two privileges that matter most, TABLE_READ_DATA and TABLE_WRITE_DATA, are the only ones that cause Polaris to issue short-lived storage credentials, and they sit outside the metadata grant that covers everything else.






- « Previous Page
- 1
- 2
- 3
- 4
- 5
- …
- 18
- Next Page »