Graph queries answer questions about relationships, such as which accounts connect to which others through a shared attribute. Those questions are awkward to express in SQL and normally require loading the data into a dedicated graph database. PuppyGraph reads Apache Iceberg tables through Dremio and presents them as a graph, so the relationship queries run against the tables you already have.
The value of the data lakehouse architecture, particularly with the Apache Iceberg table format, lies in its ability to be utilized across various systems, eliminating the need for expensive data movement and migration planning. In this article, we will explore how Apache Iceberg tables are employed within Dremio, a data lakehouse platform that serves as a central hub for analytics on structured and semi-structured data from your data lake and additional sources. We will also look at Puppygraph, a platform that facilitates the execution of graph queries on data residing in numerous locations, including Apache Iceberg tables.
Setup Our Environment
You will need docker desktop and an AWS account (for AWS Glue) to follow this exercise, open up your favorite IDE to an empty folder and create a file called docker-compose.yml with the following content:
Then you can spin up the environment with the command:
docker compose up
This will spin up Dremio and Puppygraph for our exercise.
Setting Up AWS Glue Source in Dremio
Go to locahost:9047 in your browser and create your Dremio user. Add a new “AWS Glue” data source.
Name the source “glue”, select your preferred AWS region, and enter your AWS credentials. The simplest way is to use your access key and secret key, but if you prefer using IAM roles that is also possible.
Under the advanced options tab, add a connection property with the key “hive.metastore.warehouse.dir” and the value should be the address of the location you want your data written to when Dremio creates Iceberg tables in your Glue catalog (s3://bucket/folder/).
Then click “save” to add the data source
Creating Our Tables
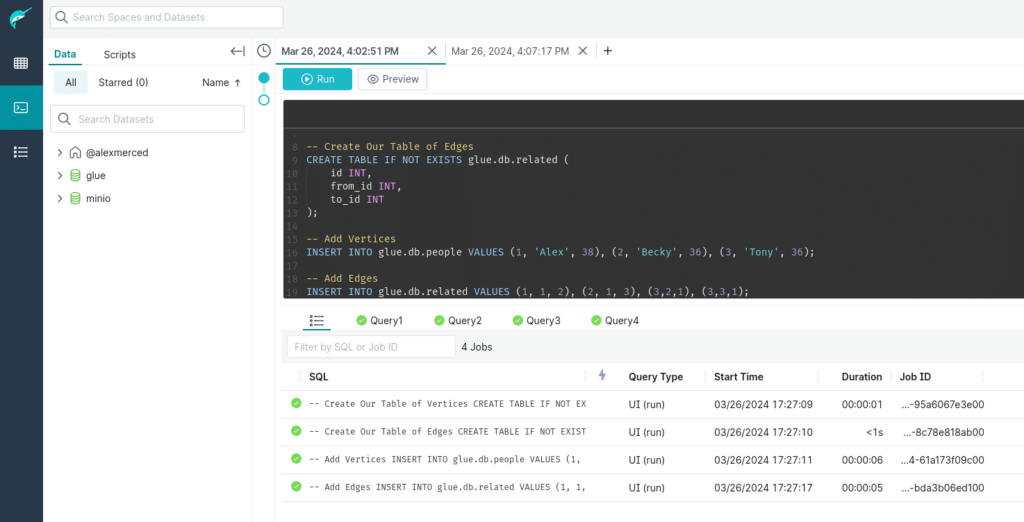
Run the following SQL to your minio source in the Dremio SQL Runner. This SQL assumes you have a database in your glue catalog called “db”.
-- Create Our Table of Vertices
CREATE TABLE IF NOT EXISTS glue.db.people (
    id INT,
    name VARCHAR(255),
    age INT
);

-- Create Our Table of Edges
CREATE TABLE IF NOT EXISTS glue.db.related (
    id INT,
    from_id INT,
    to_id INT
);

-- Add Vertices
INSERT INTO glue.db.people VALUES (1, 'Alex', 38), (2, 'Becky', 36), (3, 'Tony', 36);

-- Add Edges
INSERT INTO glue.db.related VALUES (1, 1, 2), (2, 1, 3), (3,2,1), (3,3,1);
Run this SQL, which should create the tables we need to run graph queries.
Running Graph Queries on this Data
Head over to local localhost:8081 in your browser and login to Puppygraph with username, “puppygraph” and password “puppygraph123”.
Once logged in, create a new schema and connect to your AWS Glue catalog. To use your access key and secret key uncheck the box that says “use instance profile”.
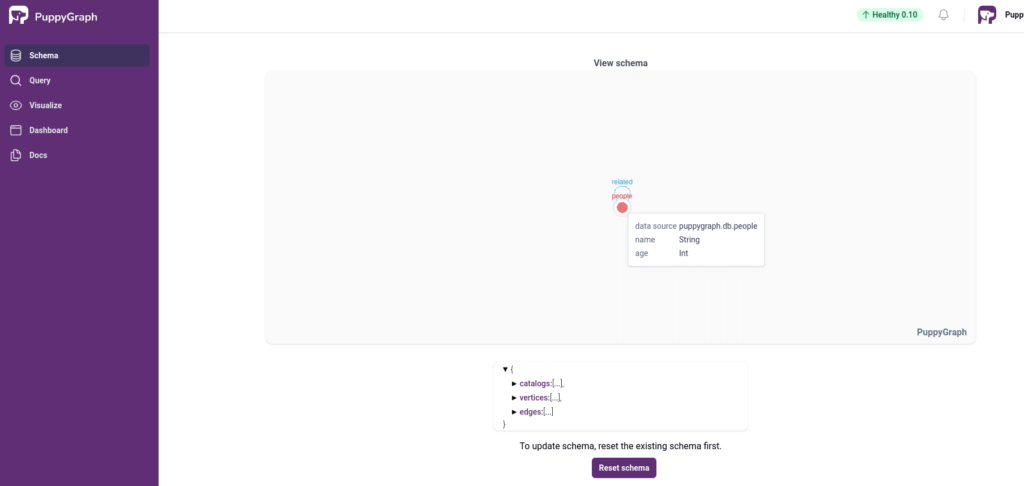
Then select the “people” table for your vertex and it should automatically have the right settings, and select the “related” table as your edge and it should also detect the right settings based on the field names, then save the schema.
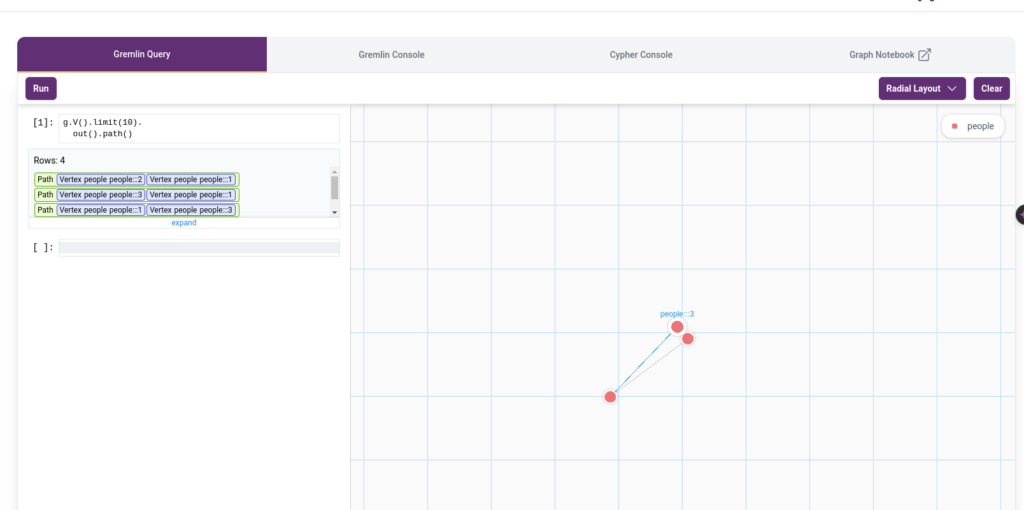
You can now query the graph using Gremlin and Cypher:
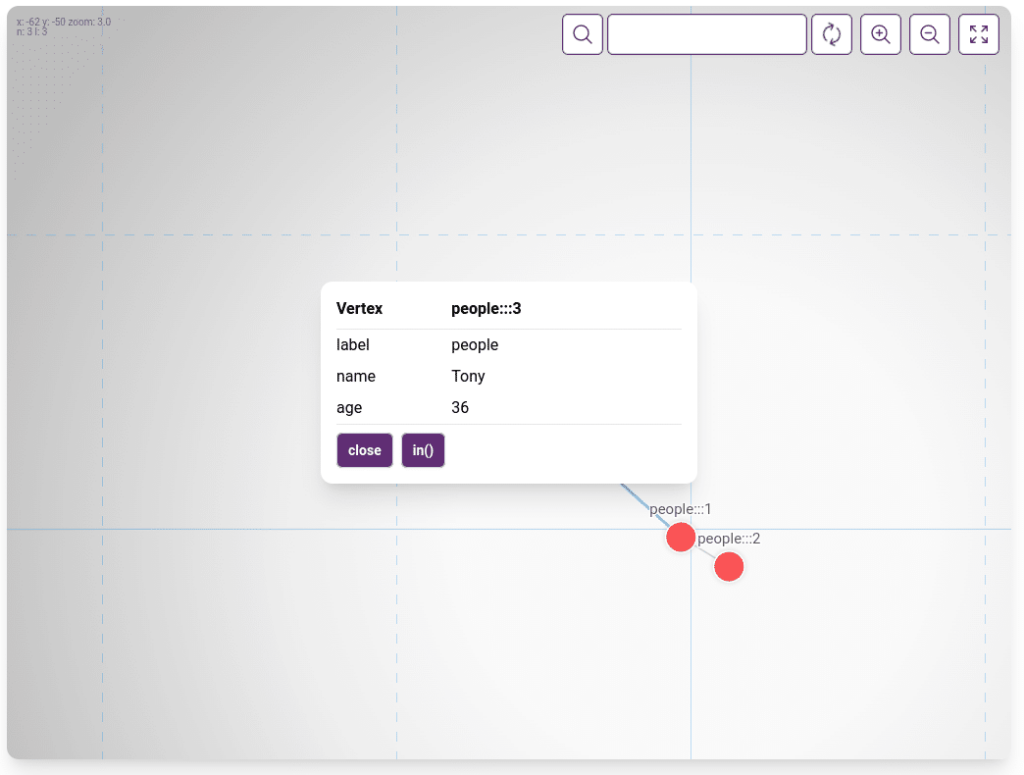
As well as using the visualizer to visualize your graph:
Conclusion
The Apache Iceberg format offers a significant advantage: it allows the same dataset to be used for SQL analytics in Dremio and for graph analytics in Puppygraph. This eliminates the need to migrate data between data warehouses and graph databases, meaning a single dataset can fulfill both requirements, provided it is modeled correctly. Utilizing a data lakehouse, we can derive greater value from our data without the burdens of data duplication and movement, optimizing both efficiency and cost-effectiveness.
For a deeper treatment of the topics in this post, download Apache Iceberg: The Definitive Guide by Tomer Shiran, Jason Hughes, and Alex Merced, free from Dremio.
Intro to Dremio, Nessie, and Apache Iceberg on Your Laptop
Editor’s note, September 2026. This post was published in September 2023 and some product details have changed since. Nessie is still available and self-deployable under the Apache-2.0 licence, and it remains the clearest implementation of catalog-level branching. It is not an Apache Software Foundation project, and its development has slowed considerably. For how the current […]
Aug 16, 2023·Dremio Blog: News Highlights
5 Use Cases for the Dremio Lakehouse
With its capabilities in on-prem to cloud migration, data warehouse offload, data virtualization, upgrading data lakes and lakehouses, and building customer-facing analytics applications, Dremio provides the tools and functionalities to streamline operations and unlock the full potential of data assets.
Sep 30, 2026·Dremio Blog: Open Data Insights
Apache Iceberg 1.12.0: What’s New, Breaking Changes, and Upgrade Guide
Apache Iceberg 1.12.0 expands v3 engine support, REST catalog operations, streaming reliability, and v4 groundwork. Learn how to upgrade safely.