The Dremio Blog
Dremio Blog: Various Insights
-

 Dremio Blog: Various Insights
Transform Studio: Free, Open Source Pipelines and Data Quality for the Dremio Community
Key Takeaways Built for the Dremio Community Transform Studio for Dremio, is a free and open source pipeline builder and data quality tool built for the Dremio community. Whether you run Dremio Cloud or a self-hosted deployment, Transform Studio gives analysts and data engineers a visual workspace to build transformation pipelines, monitor data quality, and […]
-
 Dremio Blog: Various Insights
Apache Arrow’s Role in Dremio’s Performance
Dremio is always striving to abstract away the physical concerns of data, whether the storage location, partitioning schema, or file size optimisation. Thanks to features such as Data Federation, Iceberg Clustering, and Autonomous Performance functionalities, Dremio users get highly-performant access to their data no matter where it lives. One of the components that delivers this […]
-
 Dremio Blog: Various Insights
Dremio vs. Redshift: The Cost Advantage of the Dremio Agentic Lakehouse
The New Economics of Data Cloud data warehouses like Amazon Redshift were built for a world that no longer exists. In that earlier era, organizations focused primarily on structured business intelligence, static dashboards, and predictable workloads. Data was tightly controlled, compute resources were fixed, and dynamic scalability for rapidly changing workloads was not a concern. […]
-
 Dremio Blog: Various Insights
The Value of Dremio’s End-to-End to Caching
Caching dramatically reduces latency and computational costs by storing frequently accessed data closer to where it's needed. Instead of repeated expensive operations - such as fetching from object storage, planning complex queries, or executing SQL - the data you need is provided in fast, local memory. To deliver on this, Dremio implements different layers of […]
-

 Dremio Blog: Various Insights
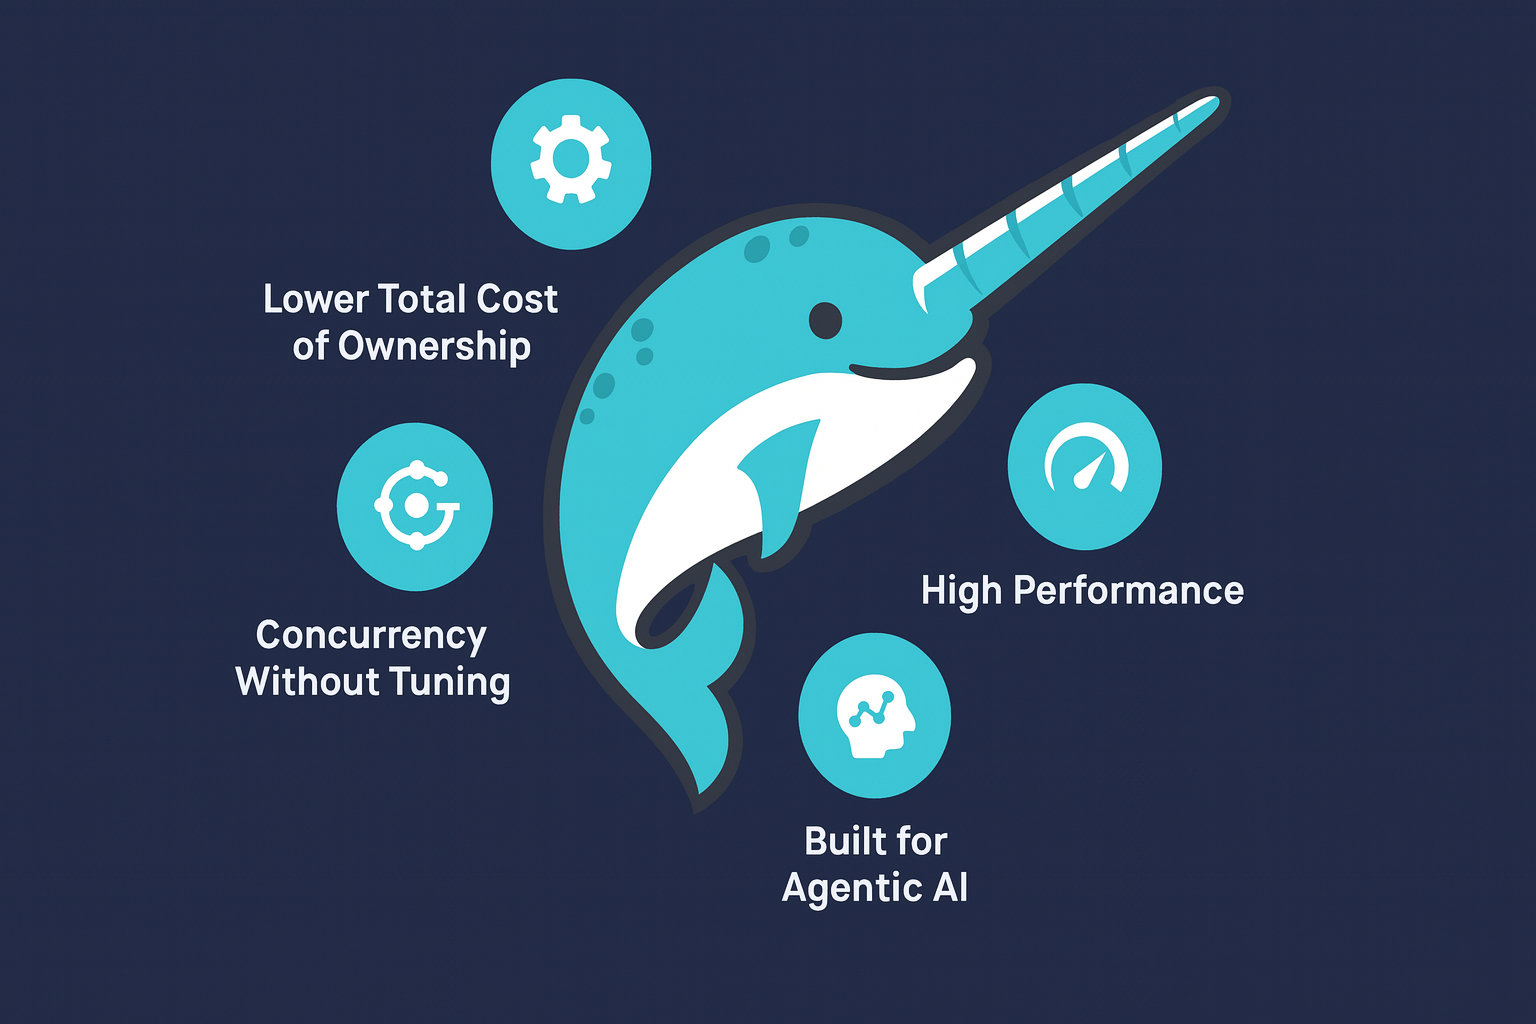
Why Dremio Outperforms Redshift: Query Speed, Concurrency, and Cost Efficiency Without Limits
The Shift from Warehouses to the Agentic Lakehouse Amazon Redshift has long been a dependable data warehouse for analytics, but the analytics landscape has evolved. Organizations are no longer just running dashboards—they’re powering agentic AI systems that reason, act, and make autonomous decisions based on live business data. These workloads demand real-time responses, high concurrency, […] -
Dremio Blog: Various Insights
A Guide to Dremio’s Agentic AI, Apache Iceberg and Lakehouse Content
This only scratches the surface of Dremio's content. Explore Dremio University and the Dremio Blog to find much more great Dremio Content. Also get involved in the Dremio and OSS community at developer.dremio.com.
-
Dremio Blog: Various Insights
Handling Complex Data Types in Dremio
Overview Dremio provides out-of-the-box methods of handling complex data types in, for example JSON and parquet datasets. Common characteristics are embedded “columns within columns” and “rows within columns”. In this blog, we will demonstrate how Dremio can discover and handle these types of data. The examples have been tested on the following Dremio versions: Preparation […]
-
Dremio Blog: Various Insights
Why Agentic AI Needs a Data Lakehouse
Agentic AI is an artificial intelligence system that is designed to operate autonomously. With minimal human supervision it can be expected to make decisions and perform tasks with specifically trained agents. This is thanks in large part to Large Language Models (LLMs) which provide agentic AI with enhanced reasoning and the ability to understand context. […]
-
Dremio Blog: Various Insights
Why Education Companies Need Secure Data Platforms: Navigating Privacy Regulations and How Dremio Helps
As education becomes increasingly data-driven, the stakes for protecting sensitive information have never been higher. Regulations like FERPA, COPPA, GDPR, and state-level privacy laws demand rigorous compliance, while rising cyber threats highlight the urgent need for robust security and governance. At the same time, educators and edtech companies cannot afford to sacrifice innovation, students expect personalized learning, administrators need real-time insights, and institutions are exploring AI-driven opportunities to improve outcomes.
-
Dremio Blog: Various Insights
From Hype to Reality: The Lakehouse as the Foundation for AI-Ready Data
The lakehouse has moved past peak hype into the part of the cycle where the question is how to run one at scale rather than whether to build one. What kept it relevant is the open table format underneath, and that same property, data readable by any engine without a copy, is what AI workloads […]
-
Dremio Blog: Various Insights
The Model Context Protocol (MCP): A Beginner’s Guide to Plug-and-Play Agents
By standardizing the interaction between hosts, clients, and servers, MCP unlocks true modularity. You can swap models without breaking workflows, mix and match servers for analytics, email, or storage, and grow your AI capabilities incrementally. The Dremio + SendGrid example shows how easily analytics and action can come together, transforming what used to be manual, multi-step processes into fully automated workflows.
-
Dremio Blog: Various Insights
Partition Bucketing – Improving query performance when filtering on a high-cardinality column
Introduction Dremio can automatically take advantage of partitioning on parquet data sets (or derivatives such as Iceberg or Delta Lake). By understanding the dataset’s partitioning, Dremio can perform partition pruning, the process of excluding irrelevant partitions of data during the query optimisation phase, to boost query performance. (See Data Partition Pruning). Partition bucketing provides a […]
-
Dremio Blog: Various Insights
The Growing Apache Polaris Ecosystem (The Growing Apache Iceberg Catalog Standard)
What makes Polaris especially exciting is the trajectory it’s on. Today, it is a powerful, open catalog for Iceberg tables. Tomorrow, it could serve as the central control plane for managing a full range of lakehouse assets, unifying governance, access, and interoperability across an increasingly complex data ecosystem.
-
Dremio Blog: Various Insights
Optimizing Apache Iceberg Tables – Manual and Automatic
When combined with Dremio’s query acceleration, unified semantic layer, and zero-ETL data federation, Enterprise Catalog creates a truly self-managing data platform—one where optimization is just something that happens, not something you have to think about.
-
Dremio Blog: Various Insights
Optimizing Apache Iceberg for Agentic AI
By using Dremio as the data gateway, organizations improve security, reduce complexity, and give their agents the reliable, performant access they need—without reinventing the data stack. This frees developers to focus less on credentials, connectors, and workarounds, and more on building the intelligent workflows that drive business impact.







- « Previous Page
- 1
- …
- 4
- 5
- 6
- 7
- 8
- …
- 10
- Next Page »