17 minute read · April 17, 2019
What Is Apache Iceberg? Features & Benefits
What Is Apache Iceberg?
Apache Iceberg is an open table format for large analytic datasets. It adds a metadata layer that gives data lake tables atomic transactions, schema and partition evolution, time travel, concurrent writes, and efficient scan planning. Engines including Dremio, Apache Spark, Apache Flink, Trino, and PyIceberg can work with the same tables through shared Iceberg metadata instead of copying data into an engine-specific format.
Reviewed September 2026 by Alex Merced. This guide reflects the Apache Iceberg v3 specification and the current multi-engine ecosystem.
The Iceberg table format brings database-style behavior to analytic datasets in object storage while allowing compatible engines to operate on the same tables. Iceberg provides many features such as:
- Transactional consistency between multiple applications where files can be added, removed or modified atomically, with full read isolation and multiple concurrent writes
- Full schema evolution to track changes to a table over time
- Time travel to query historical data and verify changes between updates
- Partition layout and evolution enabling updates to partition schemes as queries and data volumes change without relying on hidden partitions or physical directories
- Rollback to prior versions to quickly correct issues and return tables to a known good state
- Advanced planning and filtering capabilities for high performance on large data volumes
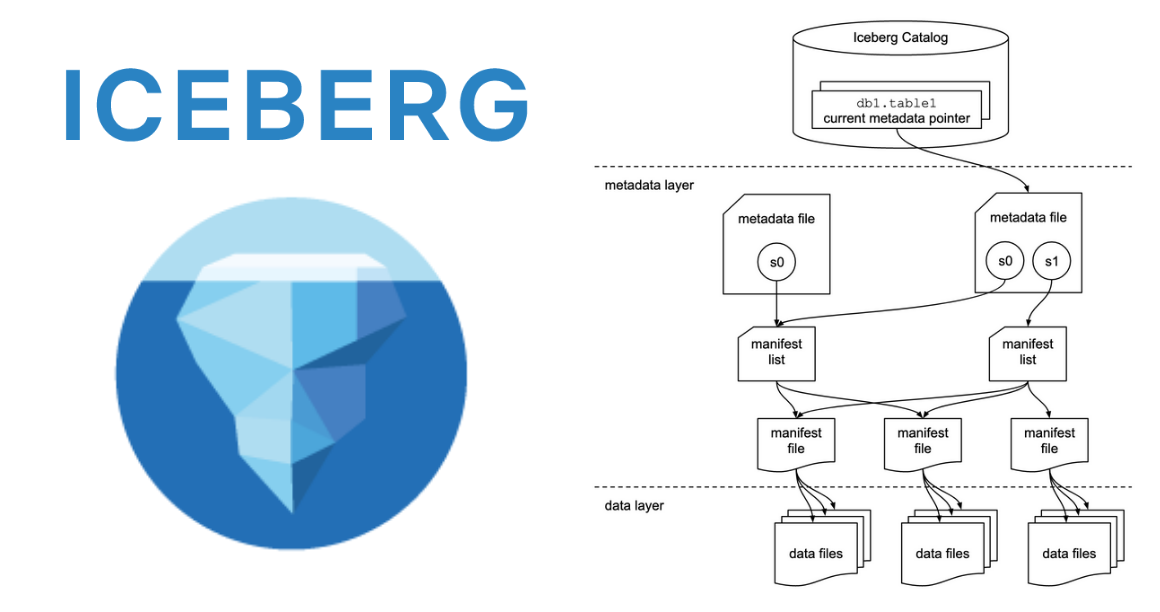
Iceberg achieves these capabilities for a table via metadata files (aka manifests) tracked through point-in-time snapshots by maintaining all deltas as a table is updated over time. Each snapshot provides a complete description of the table’s schema, partition and file information and offers full isolation and consistency. Additionally, Iceberg intelligently organizes snapshot metadata in a hierarchical structure. This enables fast and efficient changes to tables without redefining all dataset files, thus ensuring optimal performance when working at data lake scale.
With Iceberg, the full history is maintained within the Iceberg table format and without storage system dependencies. This enables an open architecture and the flexibility to change systems over time without disruption to users or existing workloads. Since the historical state is immutable and history lineage is clear, users can query prior states at any Iceberg snapshot or any historical point in time for consistent results, comparison or rollback to correct issues.
As an Apache project, Iceberg is open source under the Apache License and not dependent on any individual tools or data lake engines. It was created by Netflix and Apple, and is deployed in production by the largest technology companies and proven at scale on the world’s largest workloads and environments. Iceberg supports common industry-standard file formats, including Parquet, ORC and Avro, and is supported by major data lake engines including Dremio, Spark, Hive and Presto.
Background on Data Within Data Lake Storage
Data lakes are large repositories that store all structured and unstructured data at any scale. They are used to simplify data management by centralizing data and enabling all applications throughout an organization to interact on a shared data repository for all processing, analytics and reporting, significantly improving upon traditional architectures that rely on numerous isolated and siloed systems.
Traditionally, data lakes were associated with the Apache Hadoop Distributed File System (HDFS). Today, however, organizations increasingly utilize object storage systems such as Amazon S3 or Microsoft Azure Data Lake Storage (ADLS). These cloud data lakes provide organizations with additional opportunities to simplify data management by being accessible everywhere to all applications as needed.
Individual datasets within data lakes are often organized as collections of files within directory structures, often with multiple files in one directory representing a single table. The benefits of this approach are that data is highly accessible and flexible. However, several concepts provided by traditional databases and data warehouses are not addressed solely by directories of files and require additional tooling to define. This includes:
- What is the schema of a dataset, including columns and data types
- Which files comprise the dataset and how are they organized (e.g., partitions)
- How different applications coordinate changes to the dataset, including both changes to the definition of the dataset and changes to data
To address these, organizations utilize several industry-standard systems to further organize data within their data lake storage.
How Metadata Catalogs Help Organize Data Lakes
To better organize data within data lakes, organizations use metadata catalogs, which define the tables within data lake storage. By using catalogs, all applications across an organization share a common definition and view of data within the data lake, which is helpful for processing and producing consistent results.
Catalogs are used to define:
- What datasets exist in the data lake
- Where different datasets are located within the data lake
- How datasets are structured in terms of columns, names, data types, etc.
Hive Metastore (HMS) and AWS Glue Data Catalog are the most popular data lake catalogs and are broadly used throughout the industry. Both Hive and AWS Glue contain the schema, table structure and data location for datasets within data lake storage. In doing so, catalogs provide a similar structure as relational databases in that they are deployed on top of file storage and shared across multiple applications. This ensures consistent results between different applications and simplifies data management.
Why Catalogs Are Not Enough
Although catalogs provide a shared definition of the dataset structure within data lake storage, they do not coordinate data changes or schema evolution between applications in a transactionally consistent manner.
Consider a large dataset comprised of hundreds of thousands of files. Catalogs such as Hive and AWS Glue contain the structure of the dataset, including column names and data types, as well as partitions organized in directories. However, they do not define which data files are present and part of the dataset. As a result, applications must rely on reading file metadata in data lake storage to identify which files are part of a dataset at any given time.
As long as the dataset is static and does not change, different applications can operate on a consistent view of the dataset. However, challenges are created when one application writes to and modifies the dataset and those changes need to be coordinated with another application that reads from the same dataset. For example, if an ETL process updates the dataset by adding and removing several files from storage, another application that reads the dataset may process a partial or inconsistent view of the dataset and generate incorrect results. This occurs when some files have been added or removed from storage, but not all required changes were completed.
Without automatic coordination of data changes between applications in the data lake, organizations need to create complicated pipelines or staging areas which can be brittle and difficult to manage manually.
How Iceberg Differs from Traditional Catalogs and Databases
There are significant differences when comparing Iceberg not just to data lake catalogs such as the Hive Metastore, but to relational databases and enterprise data warehouses as well. Unlike the Hive Metastore where changes are made through Hive, with Iceberg all applications are equal participants and multiple tools can update tables directly and concurrently. Additionally, Iceberg describes the complete history of tables, including schema and data changes. The Hive Metastore only describes a dataset’s current schema without historical information or data changes with time travel.
Relational databases and enterprise data warehouses offer similar capabilities such as atomic transactions and time travel. However, they do so through a closed, vertically integrated and proprietary system where all access must go through and be processed by the database. Routing all access through a single system simplifies concurrency management and updates but also limits flexibility and increases cost. Iceberg, on the other hand, enables all applications to directly operate on tables within data lake storage. Doing so not only lowers cost by taking advantage of data lake architectures but also significantly increases flexibility and agility since all applications can work on datasets in place without migrating data between multiple separate and closed systems.
Benefits of Using Iceberg
By defining an efficient open table format for data lake tables that is transactionally consistent with point-in-time snapshot isolation, Iceberg enables numerous benefits for organizations, including:
- Multiple independent applications can process the same dataset in place simultaneously and with consistent results
- Updates to very large data lake-scale tables are efficiently processed and communicated between systems
- ETL pipelines are significantly simplified by operating on data in place in the data lake instead of moving data between multiple independent systems, resulting in pipelines that are more reliable and less resistant to change
- Improved data management as datasets change and evolve over time
- Increased data reliability and identification and resolution of issues when they arise
By using Iceberg, organizations can realize the full potential and benefits of migrating to a data lake architecture. Similar capabilities and features available with traditional databases can be provided to users but within an open and flexible data lake environment. Data engineers can simplify data pipelines and realize cost savings while providing increased access to data and performance to end users.
Apache Iceberg Engines, Catalogs, and Version Support
Iceberg separates the table format from the compute engine and the catalog. The table format defines snapshots, manifests, schemas, partitions, and data files. A catalog tracks the current table metadata location and coordinates commits. Engines read and write the table through their Iceberg connector and catalog integration.
| Layer | What it does | Examples |
|---|---|---|
| Table format | Defines table metadata, snapshots, manifests, schema evolution, partition evolution, and row-level changes | Apache Iceberg |
| Catalog | Locates tables, tracks the current metadata pointer, and coordinates commits | Apache Polaris, REST catalogs, AWS Glue, JDBC catalogs, Hive Metastore |
| Compute engine | Plans and executes reads, writes, maintenance, and SQL operations | Dremio, Spark, Flink, Trino, and other compatible engines |
| Object storage | Stores data files and Iceberg metadata files | Amazon S3, Azure Data Lake Storage, Google Cloud Storage, and compatible object stores |
Support varies by engine and version. Reading an Iceberg table does not guarantee support for every write operation or every v3 feature. Check the Apache Iceberg v3 engine support matrix before using deletion vectors, row lineage, VARIANT values, geospatial types, or other newer capabilities in a multi-engine environment.
Apache Iceberg Implementation Guides
- Apache Iceberg vs. Delta Lake
- How the Iceberg REST Catalog works
- Compacting Apache Iceberg tables
- Copy-on-write vs. merge-on-read
- Apache Iceberg v2 vs. v3
- Apache Iceberg v3 engine support matrix
When Should You Use Apache Iceberg?
Iceberg is a strong fit when large analytic tables live in object storage, multiple engines need consistent access, schemas and partitions change over time, or teams need reliable updates and historical queries without loading data into a proprietary storage layer. It is less useful for small operational databases, millisecond point lookups, or workloads that do not need table-level transactions and metadata management.
For implementation details, see how the Iceberg REST Catalog standardizes catalog access and how to monitor Iceberg table health with metrics reports and metadata tables.
Alternatives to Iceberg
Apache Iceberg, Delta Lake, Apache Hudi, and Hive ACID tables all bring database-style management to files in a data lake, but they differ in governance, engine support, and operational design. The right choice depends on the engines you run, the write patterns you need, and how important independent governance and cross-engine portability are to your architecture.
| Project | Governance | Typical strength | Evaluation question |
|---|---|---|---|
| Apache Iceberg | Apache Software Foundation | Broad multi-engine analytics, hidden partitioning, metadata-based planning, and open catalog integrations | Do all required engines support the Iceberg features and write operations you plan to use? |
| Delta Lake | Linux Foundation project with strong Databricks and Spark roots | Deep integration with Spark and the Databricks ecosystem | Will every required engine provide the same level of read and write support? |
| Apache Hudi | Apache Software Foundation | Incremental processing and ingestion-oriented workflows | Does the operational model match your update frequency and query engines? |
| Hive ACID | Apache Software Foundation | Transactional tables in Hive-oriented environments | Is the workload centered on Hive and ORC, or does it require broader engine portability? |
Compare current connector documentation and test the operations that matter to your workload. Project-level feature lists can hide differences in engine versions, catalog behavior, maintenance procedures, and support for row-level changes.
Advantages of Iceberg Over Other Formats
Although there are multiple table format options available, Iceberg shares key attributes with previous open source projects that became de facto industry standards such as Apache Parquet. In particular, Iceberg is entirely independent from a governance standpoint and is not locked or tied to any specific engine or tool. As a result, Iceberg can be developed and contributed to by many different organizations across multiple industries, increasing adoption and growth. Additionally, Iceberg has several advantages, including:
- All applications have equal access and processing is not dependent on or tied to any specific engine, providing organizations with the flexibility to customize their data lake as needed
- Performance optimizations based on best practices which enable fast and cost-efficient access to data
- Fully storage-system agnostic with no file system dependencies, offering flexibility when choosing and migrating storage systems as required
- Multiple successful production deployments with tens of petabytes and millions of partitions
- 100% open source and independently governed
As a result of these advantages, Iceberg is rapidly gaining adoption and helping organizations simplify management and take full advantage of their data lake.
Get a Free Early Release Copy of "Apache Iceberg: The Definitive Guide".
Try Dremio’s Interactive Demo
Explore this interactive demo and see how Dremio's Intelligent Lakehouse enables Agentic AI